Prepare your photos and words, then review the available settings and credit quote in the studio. Saving a draft does not spend credits.
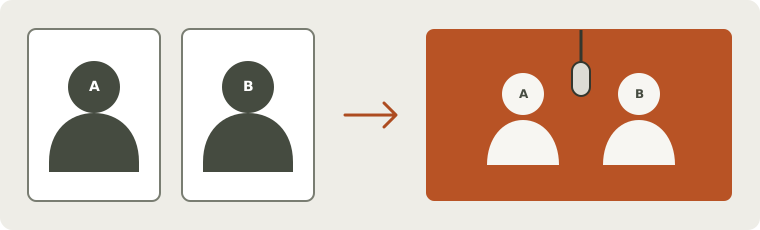
Input arrangement illustration — not photos or a generated result.
You do not need to film together
For separate inputs, use one performer in each photo. Photo 1 maps to the left position and photo 2 to the right. For a shared photo, the source image’s left-to-right order is used. Similar camera height and unobstructed faces make the references easier to inspect.
The studio checks for up to two people, cats or dogs. If the photo is unclear or too crowded, it will ask you to review it or choose another. Check the faces again in the finished video.
Same frame, different performance roles
Choose alternating leads for a short exchange, or one lead with a moving and reacting partner. Shared lyrics and separately assigned left/right lyrics are available in the editor. Swapping separate photos also swaps names, assigned words and lead position.
These settings guide who leads and which words they sing. The result can differ: listen for both parts and watch who sings at each handoff.
Same frame, different performance roles
Setting
What it asks for
What still needs checking
One lead + partner
One side delivers the verse; the other reacts
The partner does not mouth the entire verse
Alternating leads
A short exchange between the two sides
Voices and mouths switch at the intended moments
Assigned lyrics
Different text for each side
The actual words stay with the intended person
Both people share one short clip
Write one brief line per person first. The two sets of lyrics share the same total duration and word budget; each person does not get a whole clip’s worth of text. Optional names and pronunciation notes also need room in the performance.
For example, one person can open with a friendly birthday wish and the other answer with a short inside joke. These are writing ideas, not recordings or a guarantee of precise turn-taking.
Check both people before sharing
Play the finished video with sound. Listen to your words and names, and watch how both people take their parts. Download a copy you like before its expiry.
Check the credits for your model, length and resolution before submitting. Saving a draft is free; generation access is shown in the studio.
Real generated examples
Explore complete performances made with fictional adult references in the studio. Each video includes its original photos, words and settings.
Two portraits, two assigned lines
Input images
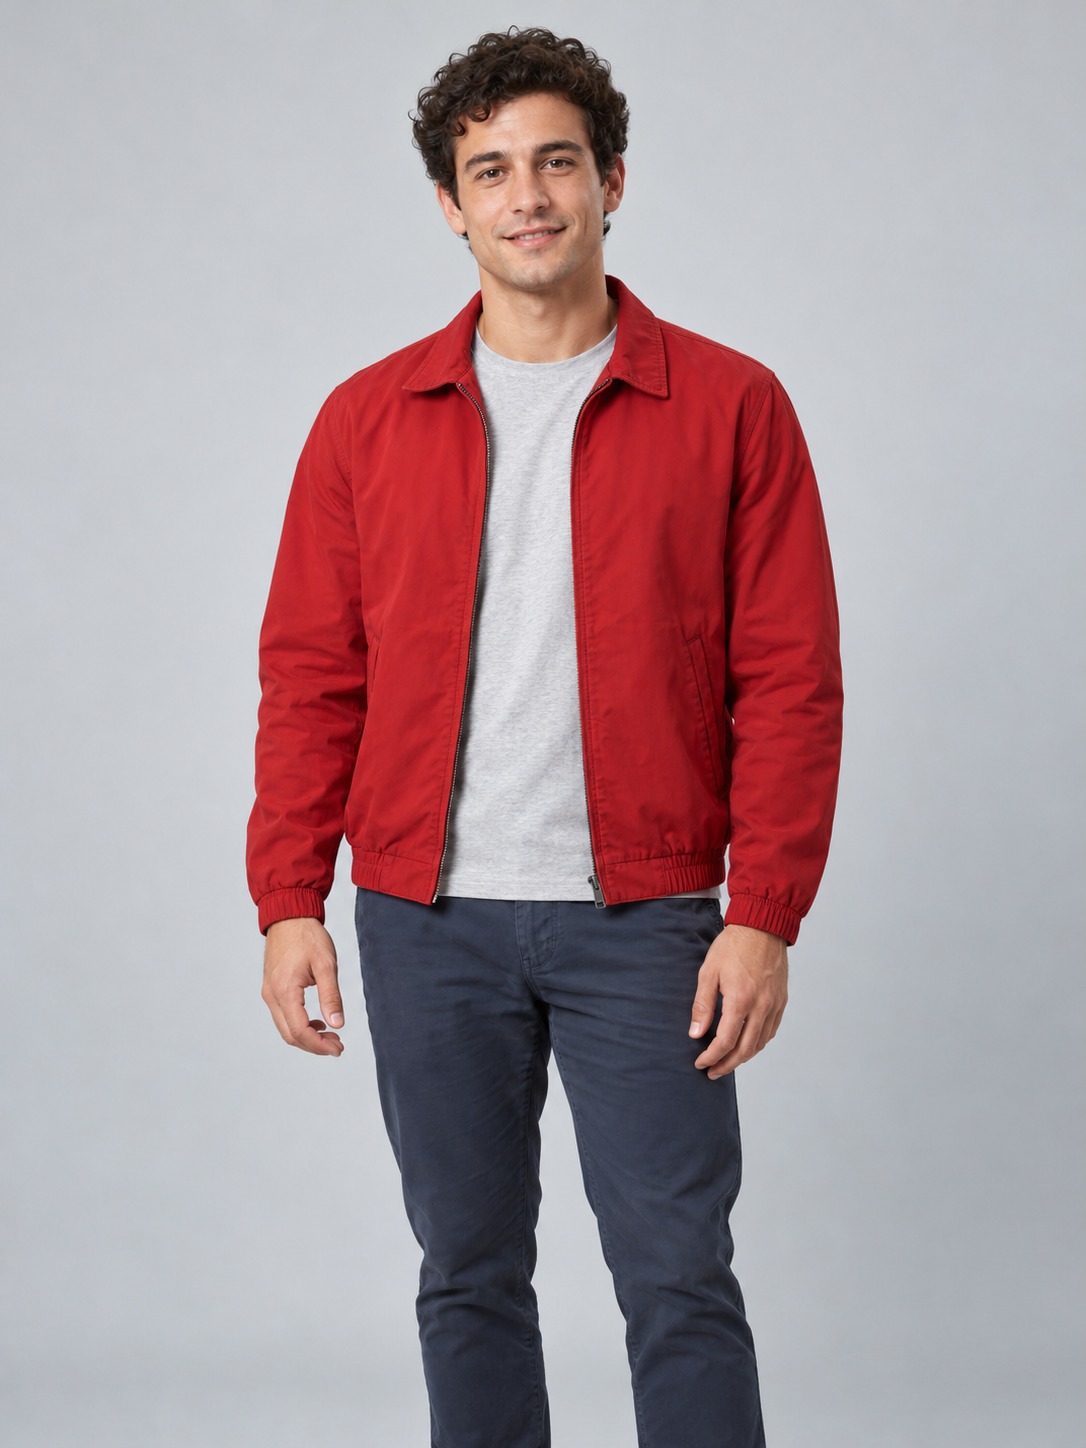
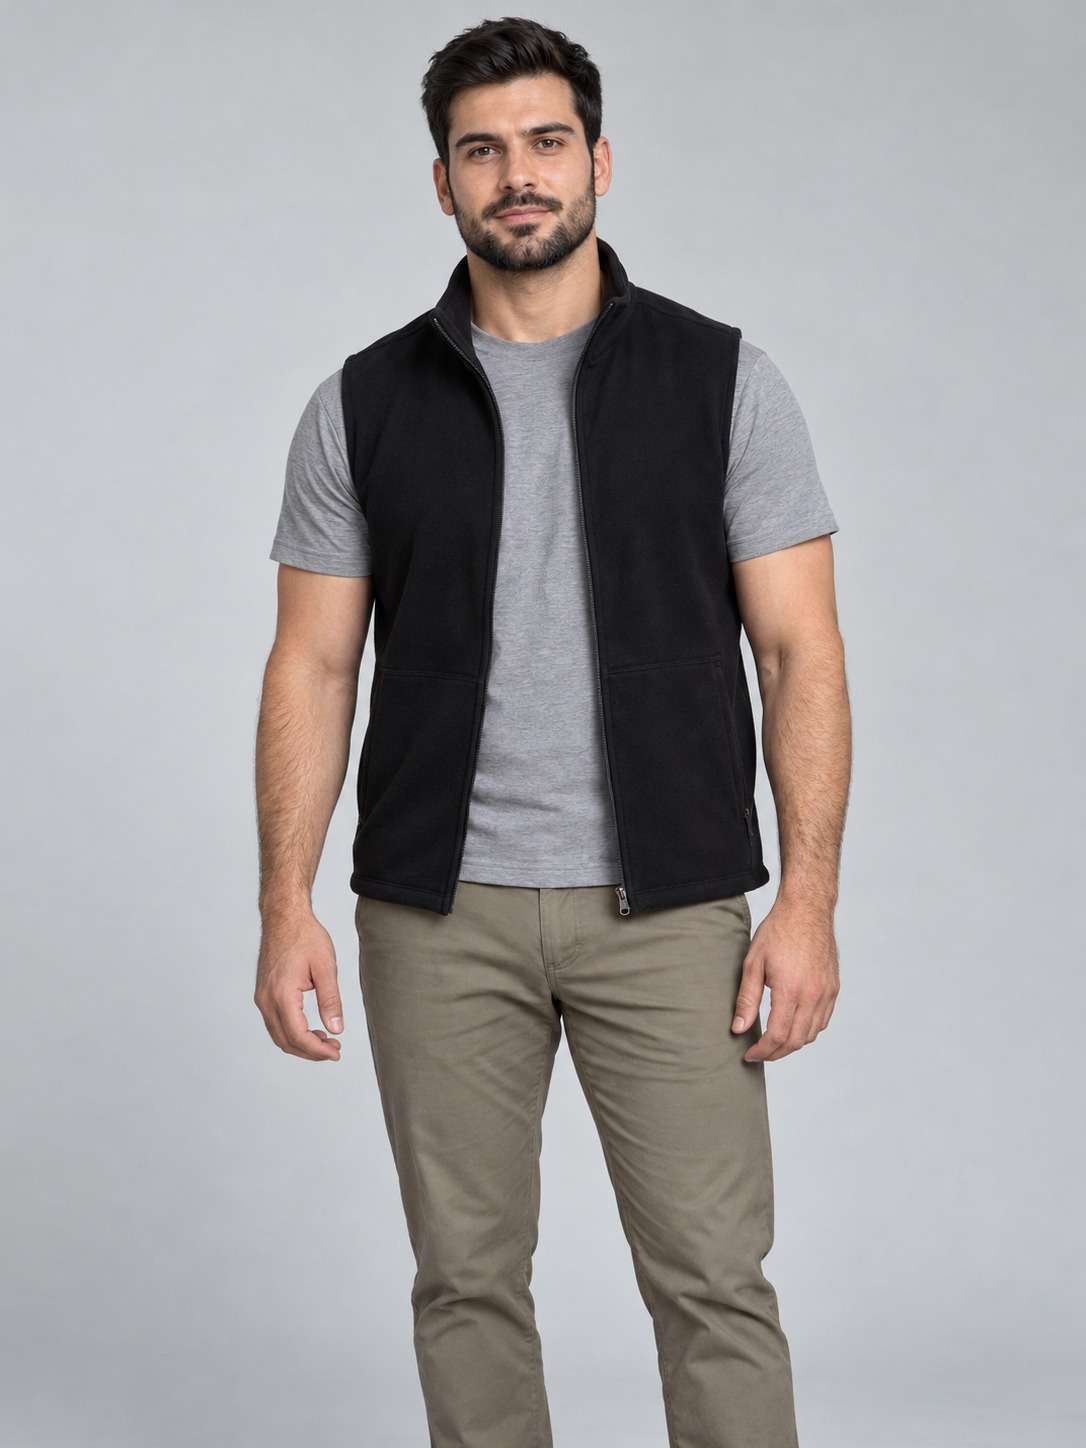
Photo 1 / leftPhoto 2 / right
Original synthetic adult portrait references.
Requested English lyrics
Alex: Alex brings the rhythm, Jamie brings the light.
Jamie: Two good friends together, make the moment bright.
The selected retry uses two separate synthetic portraits and the same assigned lyrics as the first attempt. Both identities and their left/right order remain recognizable.
The left performer mainly delivers the first complete line, followed by the right. Whisper recognized both supplied lines without the first attempt’s repeated phrase.
Native playback, file specifications and basic audio–visual alignment were checked. This is a scoped demonstration, not an acceptance of all custom duo generations.
Limits of this example
Both performers hold a finger near the face for much of the clip; movement is limited. Offline analysis estimates roughly 120–160 ms offset in the leading sections, so lip sync is not exact.
Vosk truncates “bright” and additionally reports “it’s just” near the end, while Whisper does not. Compare the original audio; neither decoder proves word-for-word accuracy. This is one English / Orange Booth / Fast / 720p / 10s retry.
Offline English transcription
Alex brings the rhythm, Jamie brings the light Two good friends together make the moment bright
Automatic transcription can mishear words. Play the complete recording to compare.
Two performers from one shared image
Input images
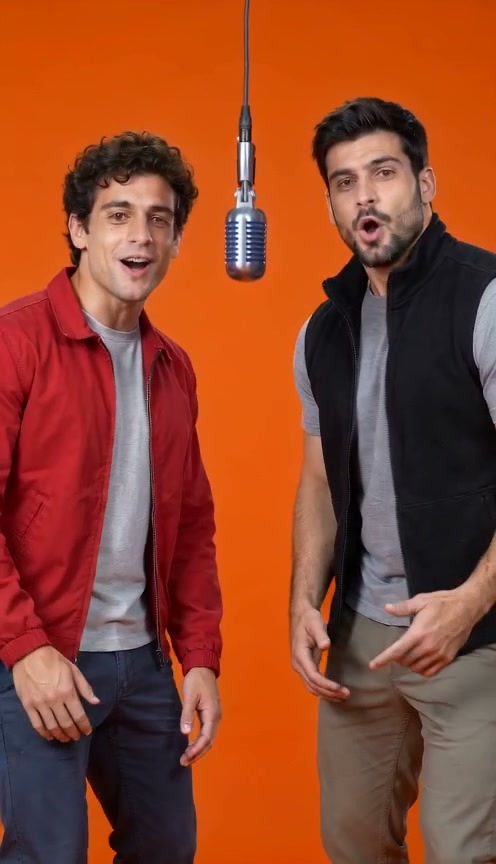
One file containing both people
One complete frame from an earlier AI-generated video. This is a synthetic two-person image.
Requested English lyrics
Alex: Alex brings the rhythm, Jamie brings the light.
Jamie: Two good friends together, make the moment bright.
One actual submitted file contains both synthetic adults. Their left/right order and recognizable faces remain consistent in the inspected sequences.
The left performer mainly leads the first line and the right mainly leads the second; basic offline alignment supports those sections.
Whisper recognized the supplied words; Vosk heard “light” as “lie”. The full video played with sound and its browser download matches the stored original.
Limits of this example
The source is a complete frame from an earlier AI video, not a camera group photo. This result does not validate every real photograph.
Transcription disagreement and occasional mouth movement while reacting prevent a word-perfect or strict speaker-attribution claim. This is one English / Orange Booth / Fast / 720p / 10s result.
Offline English transcription
Alex brings the rhythm Jamie brings the light two good friends together make the moment bright
Automatic transcription can mishear words. Play the complete recording to compare.
Questions before you start
Can the portraits be taken separately?
Yes. You can prepare one independent photo per person; there is no need to record together.
Can I use one photo of a couple?
Yes, if both people are clearly visible. Shared photos and separate portraits can give different results, so check both faces and the performance. The example below uses a synthetic two-person image, not a camera photo.
Can I control exactly who says every line?
You can assign words and request alternating leads. Exact voice separation, wording and turn order are output checks, not guarantees from the text settings.
Can two photos sing an entire song together?
This product focuses on short rap performances. Duo controls do not establish full-song harmony or exact performance of an uploaded song.